GPT-6.1 Sol is an upgrade to GPT-6 Sol from OpenAI, positioned below the flagship GPT-6 Astra in the GPT-6 series.
- Image input
- Tool calling
- PDF input
- Reasoning mode
- Adjustable reasoning effort
 GPT-6.1 SolOpenAI · chat1M context
 Claude Sonnet 5.5Anthropic · chat1M context
 Gemini 3.8 FlashGoogle · chat1M context
 Grok 4.7xAI · chat500K context
 DeepSeek V4.1 FlashDeepSeek · chat1M context
 GLM 5.3 PrimeZ-AI · chat1M context
 Kimi K3MoonshotAI · chat1M context
 Qwen3.8 Max PrimeQwen · chat1M context
 Llama 4 MaverickMeta · chat1M context
 Mistral Medium 3.5Mistral · chat262K context
 MiniMax M2.7MiniMax · chat204K contextGPT-6 LunaOpenAI · chat1M contextClaude Opus 5.5Anthropic · chat1M contextGemini 3.7 FlashGoogle · chat1M contextGrok 4.6xAI · chat500K contextDeepSeek V4 Pro 0423DeepSeek · chat1M context
 Nano Banana 2.1Google · image~12s per imageGPT Image 2.5 SunburstOpenAI · image~60s per image
 Flux 2Black Forest Labs · image~5s per imageFlux 2 ProBlack Forest Labs · image~10s per imageNano BananaGoogle · image~8s per image
 Seedance 2.0 FastByteDance · video4–15s · 720pSeedance 2.0ByteDance · video4–15s · 720p
 Kling StandardKuaishou · video3–15s · 720pKling ProKuaishou · video3–15s · 720p
 Veo 3.1 FastGoogle · video4–8s · 4KKimi K3MoonshotAI · chat1M contextQwen3.8 Max PrimeQwen · chat1M contextLlama 4 MaverickMeta · chat1M contextMistral Medium 3.5Mistral · chat262K contextMiniMax M2.7MiniMax · chat204K contextGPT-6 LunaOpenAI · chat1M contextClaude Opus 5.5Anthropic · chat1M contextGemini 3.7 FlashGoogle · chat1M contextGrok 4.6xAI · chat500K contextDeepSeek V4 Pro 0423DeepSeek · chat1M contextNano Banana 2.1Google · image~12s per imageGPT Image 2.5 SunburstOpenAI · image~60s per imageFlux 2Black Forest Labs · image~5s per imageFlux 2 ProBlack Forest Labs · image~10s per imageNano BananaGoogle · image~8s per imageSeedance 2.0 FastByteDance · video4–15s · 720pSeedance 2.0ByteDance · video4–15s · 720pKling StandardKuaishou · video3–15s · 720pKling ProKuaishou · video3–15s · 720pVeo 3.1 FastGoogle · video4–8s · 4KGPT-6.1 SolOpenAI · chat1M contextClaude Sonnet 5.5Anthropic · chat1M contextGemini 3.8 FlashGoogle · chat1M contextGrok 4.7xAI · chat500K contextDeepSeek V4.1 FlashDeepSeek · chat1M contextGLM 5.3 PrimeZ-AI · chat1M contextClaude Opus 5.5Anthropic · chat1M contextGemini 3.7 FlashGoogle · chat1M contextGrok 4.6xAI · chat500K contextDeepSeek V4 Pro 0423DeepSeek · chat1M contextNano Banana 2.1Google · image~12s per imageGPT Image 2.5 SunburstOpenAI · image~60s per imageFlux 2Black Forest Labs · image~5s per imageFlux 2 ProBlack Forest Labs · image~10s per imageNano BananaGoogle · image~8s per imageSeedance 2.0 FastByteDance · video4–15s · 720pSeedance 2.0ByteDance · video4–15s · 720pKling StandardKuaishou · video3–15s · 720pKling ProKuaishou · video3–15s · 720pVeo 3.1 FastGoogle · video4–8s · 4KGPT-6.1 SolOpenAI · chat1M contextClaude Sonnet 5.5Anthropic · chat1M contextGemini 3.8 FlashGoogle · chat1M contextGrok 4.7xAI · chat500K contextDeepSeek V4.1 FlashDeepSeek · chat1M contextGLM 5.3 PrimeZ-AI · chat1M contextKimi K3MoonshotAI · chat1M contextQwen3.8 Max PrimeQwen · chat1M contextLlama 4 MaverickMeta · chat1M contextMistral Medium 3.5Mistral · chat262K contextMiniMax M2.7MiniMax · chat204K contextGPT-6 LunaOpenAI · chat1M contextFlux 2Black Forest Labs · image~5s per imageFlux 2 ProBlack Forest Labs · image~10s per imageNano BananaGoogle · image~8s per imageSeedance 2.0 FastByteDance · video4–15s · 720pSeedance 2.0ByteDance · video4–15s · 720pKling StandardKuaishou · video3–15s · 720pKling ProKuaishou · video3–15s · 720pVeo 3.1 FastGoogle · video4–8s · 4KGPT-6.1 SolOpenAI · chat1M contextClaude Sonnet 5.5Anthropic · chat1M contextGemini 3.8 FlashGoogle · chat1M contextGrok 4.7xAI · chat500K contextDeepSeek V4.1 FlashDeepSeek · chat1M contextGLM 5.3 PrimeZ-AI · chat1M contextKimi K3MoonshotAI · chat1M contextQwen3.8 Max PrimeQwen · chat1M contextLlama 4 MaverickMeta · chat1M contextMistral Medium 3.5Mistral · chat262K contextMiniMax M2.7MiniMax · chat204K contextGPT-6 LunaOpenAI · chat1M contextClaude Opus 5.5Anthropic · chat1M contextGemini 3.7 FlashGoogle · chat1M contextGrok 4.6xAI · chat500K contextDeepSeek V4 Pro 0423DeepSeek · chat1M contextNano Banana 2.1Google · image~12s per imageGPT Image 2.5 SunburstOpenAI · image~60s per image
Every model in Omny: 132 for chat, 14 for images and 8 for video. Open one to see what it does, or ask several the same question at once.
Chat with any of them, or put several on the same prompt and keep the best answer. Each family leads with its latest release.
OpenAI · 41 models
GPT-6.1 Sol is an upgrade to GPT-6 Sol from OpenAI, positioned below the flagship GPT-6 Astra in the GPT-6 series.
Anthropic · 15 models
Claude Sonnet 5.5 is Anthropic's Sonnet-class model for well-scoped everyday work, succeeding Claude Sonnet 5 as a direct upgrade.
Google · 9 models
Gemini 3.8 Flash is Google's most intelligent Flash model with significant gains from 3.7 Flash across software engineering, agentic tasks, and multi-step reasoning.
xAI · 5 models
Grok 4.7 is SpaceXAI's flagship model for coding, agentic tasks, and knowledge work, succeeding Grok 4.6.
DeepSeek · 9 models
DeepSeek V4.1 Flash is a sparse mixture-of-experts model from DeepSeek, and the first built on the company's Causal Encoder-Decoder (CED) architecture.
Z-AI · 12 models
GLM-5.3-Prime is the high-speed variant of Z.ai's GLM-5.3, inheriting its full capabilities while delivering 1.5–2× the output throughput through inference acceleration.
MoonshotAI · 5 models
Moonshot's 2.8T multimodal flagship for long-horizon agent work.
Qwen · 23 models
Qwen3.8 Max Prime is a higher-throughput variant of Qwen3.8 Max from Alibaba's Qwen team, served as a separate SKU at a higher price point.
Meta · 3 models
Meta's 400B MoE flagship for open multimodal AI.
Mistral · 6 models
Mistral Medium 3.5 is a dense 128B instruction-following model from Mistral AI.
MiniMax · 4 models
MiniMax-M2.7 is a next-generation large language model designed for autonomous, real-world productivity and continuous improvement.
Real samples from each model. Generate from a prompt, or edit with reference images.
 Max plan
Nano Banana 2.1
 Max plan
GPT Image 2.5 Sunburst
OpenAI
 Pro plan
Flux 2
Black Forest Labs
 Max plan
Flux 2 Pro
Black Forest Labs
 Pro plan
Nano Banana
 Pro plan
Seedream v4.5
ByteDance
 Pro plan
GPT Image 1.5
OpenAI
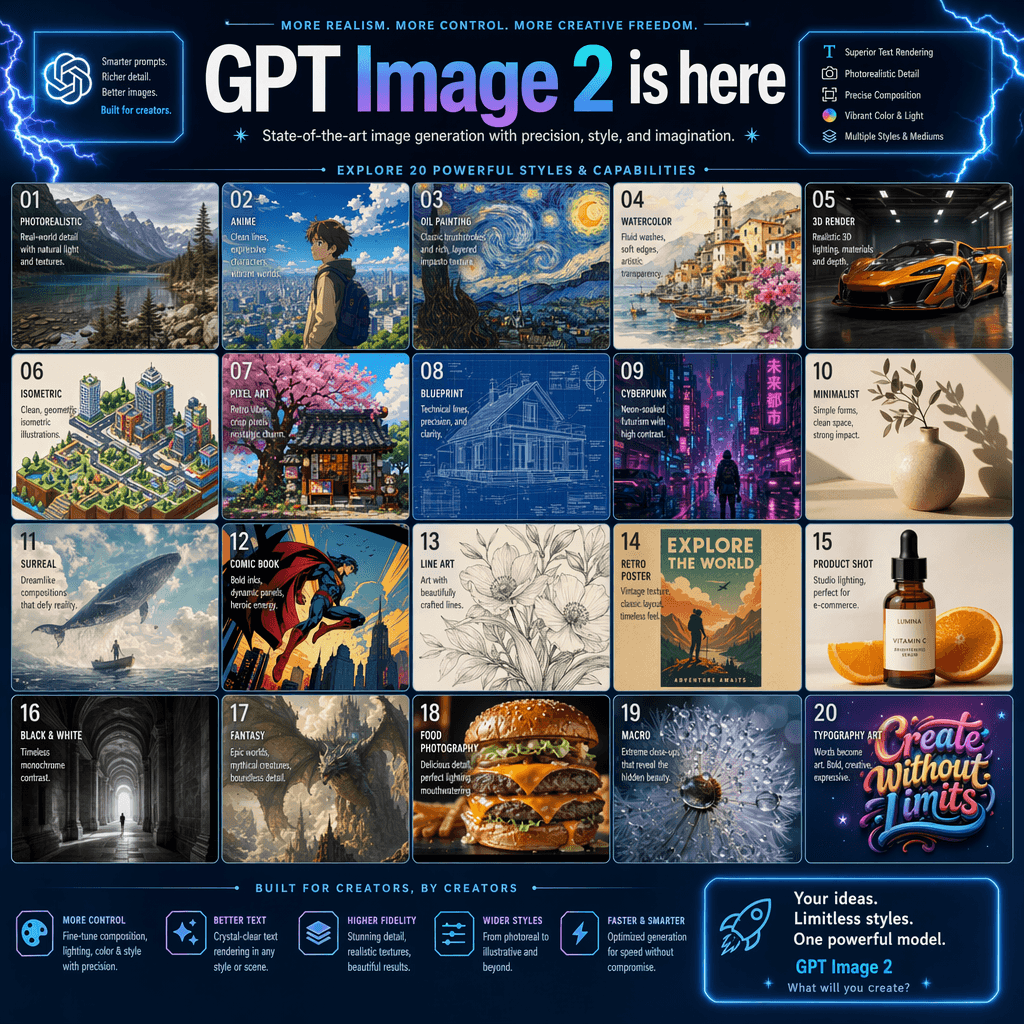 Max plan
GPT Image 2
OpenAI
 Max plan
Nano Banana 2
 Ultra plan
Nano Banana Pro
Stills from real clips. Text to video, and image to video where the model supports it.
 Pro plan
Seedance 2.0 Fast
ByteDance
 Max plan
Seedance 2.0
ByteDance
 Pro plan
Kling Standard
Kuaishou
 Max plan
Kling Pro
Kuaishou
 Max plan
Veo 3.1 Fast
 Ultra plan
Veo 3.1
 Ultra plan
FLUX 3 Video
Black Forest Labs
 Pro plan
Grok Imagine
xAI
Run any prompt on GPT, Claude and Gemini side by side. No account needed for your first answers.
